Nonstop AI™ For Faster
Agentic Inference
Nonstop AI™ clusters, servers, and data interfaces that move data 10x lower latency and 10x efficiency for 10x faster inference. Any compute, acceleration, or data, your choice.
Delos Nonstop AI™ Clusters
Architect, validate, and run resilient AI capacity at scale. Get full-stack observability and hitless failure detection deployed on any compute, acceleration, model, connectivity, or topology.
Architect
Use the Nonstop AI Reference Architecture to design a cluster around a mixture of hardware, models, and topologies working as one domain — the blueprint for everything that follows.
Delos Nonstop AI™ Server
Disaggregated scale-up connectivity for 1000x higher scale AI clusters delivering faster, stronger and optimized AI capacity.
Choose Every Component
Diverse inference workloads need diverse platforms. The Server works with any switch, or cable, so a cluster can mix GPUs, XPUs, accelerators, and CPUs freely.
Delos Nonstop AI™ Data Interface
The data interface silicon that connects any GPU, XPU, Accelerator, data memory, or data storage, into one low-latency, high-performance, resilient domain.
I/O Chiplet
Co-packaged directly into next-generation GPUs, XPUs and accelerators, delivering over 30 terabits per second of multi-protocol I/O bandwidth: the fastest, tightest integration the Data Interface silicon offers.
The Reference Architecture Connecting It All
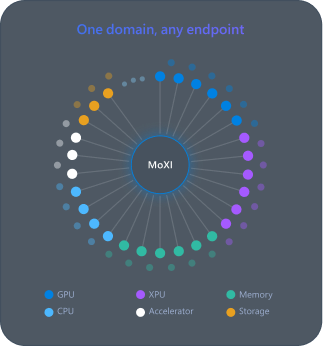
MoXI is Delos Data's reference architecture for a mixture of everything an agentic inference workload actually needs: a mixture of hardware (GPUs, XPUs, CPUs, accelerators, memory, and storage), a mixture of models running side by side, and a mixture of physical layers, switches, and topologies, all working as one domain. Mosaic, the Server, and Apollo are each built against this same architecture, so choosing any one of them, or all three together, never means locking into one vendor's hardware, one topology, or one interconnect standard.
Let's get the conversation started.


